News
From prompts to loops: how AI entered every stage of my data journalism
Since the arrival of ChatGPT, news organisations have experimented with AI in almost every corner of their operations. We have been tracking and reporting on some of these use cases, from fact-checking and investigations to data analysis, graphic creation, audience engagement and newsroom automation. But as experimentation continues, it can be difficult to see the bigger picture: where is AI actually being adopted, how are news organisations using it, and what patterns are beginning to emerge?
Jindex.ai tracks how news and media organisations around the world are adopting AI, collecting around 20 different parameters and adding an insights layer that allows users to identify patterns across organisations, markets and geographies. The data is gathered from across the web through a combination of manual research, automated searches and AI-assisted methods, with the methodology continually evolving as new tools and approaches emerge. Here are some insights that have already emerged from the database:
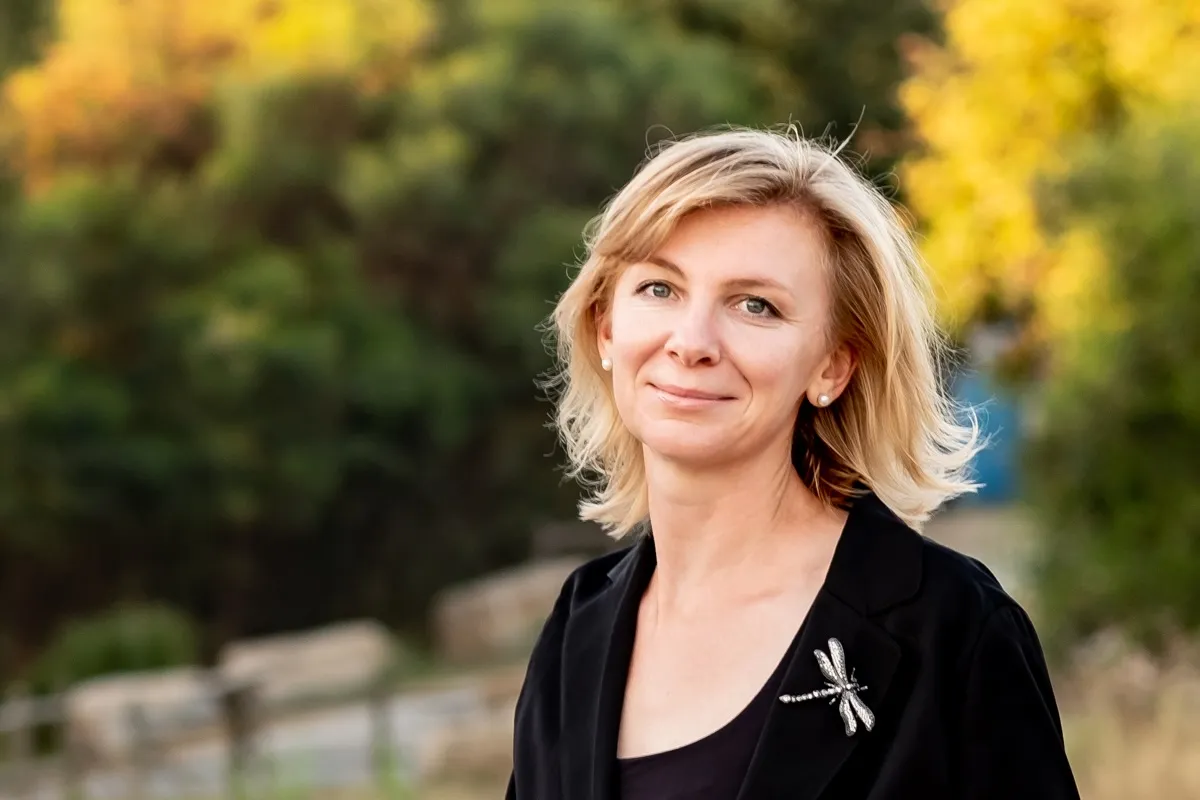
The brain behind Jindex.ai (and these insights) is Ukrainian journalist Katya Gorchinskaya, who has spent three decades in the industry as a reporter, editor, chief executive, and now as a media consultant specialising in AI.
I recently spoke to her about the database. We discussed what the data reveals about AI adoption and what those patterns might tell us about the future of the industry. Gorchinskaya stressed her database is not a complete list of AI projects, and is only based on what’s publicly available. Our conversation was edited for length and clarity.
Q. J·Index includes more than 3,000 examples of how news organisations use AI. What have you learned that you didn’t know before starting the database?
A. There are days when I literally generate insights faster than I can digest them, and sometimes they are completely unexpected.
For example, I started seeing that everybody is deploying AI editorial assistants, but there seems to be a recurring theme in how they are doing it, in the structure of it. For example, I noticed that editorial assistants being developed by different news organisations tend to have the same basic structure.
They are grounded in some form of data, such as a publisher’s archive or specific editorial rules, and sit on top of one or more AI models. They then have a set of functions — from drafting and archive searches to transcription and spellchecking — and an interface where journalists interact with them, either through a separate app or directly within the CMS.
The most sophisticated systems also have an orchestration (or agentic) layer that coordinates multiple agents performing different editorial tasks. This basic structure repeats across the different builds we see in the database.
Once you start digging into it, you find cool things like that. One of the recent widgets that I added came from reading that publishers are hoping for deals with model makers, but they actually shouldn’t because the deals [with individual companies] are done. That’s it. The market is closed, and you can see that in the data.
Q. What patterns do you see emerging?
A. Very typically, most organisations will start automating in the newsroom, and the reason for that is because we are content matter specialists. Journalists know their product best, and this is what they start automating. Plus, they are automating with the help of a large language model, which is a natural fit for anything that’s language-based.
Around 60% of all rollouts of AI cases are still in the newsroom, which also shows a huge opportunity still underused on the commercial side and across other elements of the business model. It also shows you the direction of travel strategically: where media organisations are going to go from now on. This is a prediction that you can make quite safely based on the data and how it unrolls.
There is also a real difference between early adopters and heavily-resourced adopters. Typically, the latter start early and are a lot more systematic. There are already teams involved, and there is a pattern to how they do it versus what you see with smaller organisations, that are typically donor-based or something along those lines.
Q. Does size matter?
A. It does. For example, I have a section on open-source tools in J·Index, and all of those cases come from donor-funded organisations. People who get money from media development organisations are a lot more likely to share their tools openly, as opposed to commercial organisations that might monetise their tools and sell them as a product to other news organisations.
Big giants also tend to have the resources to understand the opportunities much better, understand the weaknesses of their own organisations, and design strategies deeply rooted in that understanding. They roll out AI tools in a much more systematic way.
On top of their current strategies, they also think about what’s on the horizon. They understand, for example, that there is a new business model somewhere beyond the horizon, even if we don’t know what it is.
They spend a lot of time thinking about the value chain that is going to exist there and how to monetise it, while protecting today’s model and automating elements of it to make it more efficient, faster and more adaptive to changing consumption patterns. Smaller media organisations tend to underestimate the disruptive potential of AI and employ one tool or one workflow at a time.
Q. J·Index tracks what newsrooms build versus the tools they buy. What have you learnt about this?
A. The current disruption started 15 to 20 years ago. We know where the power sits, and it’s exactly the same. Tool dependency means that you are going to be dependent on systems designed beyond your control, and that is very sad.
Some organisations do account for that and train their own models. Others build a single internal system that sits on top of several model providers, so staff can switch the underlying model without changing the tool they are using. The model is decoupled from the interface, which allows them to use the best or cheapest model for a particular task and reduces their dependency on any one provider. Examples include France Télévisions, medIAGen, News Corp Australia and NewsGPT. But by far the more common approach is to run separate tools, each based on a different underlying model — for example, Whisper for transcription, GPT for chatbots and an image generator based on a diffusion model.
Then there’s cognitive dependency, which is something people are not paying enough attention to, perhaps because it’s not necessarily very obvious. If you outsource a lot of your brain work to the machine, you are going to lose skills in the long run.
Model makers say that most of the models are now in the recursive self-improvement stage of their development, and I feel that journalists need to adopt a similar approach. Unless you have some experience, unless you train people in basic skills, it’s very easy to lose those skills and lose judgment. I have already seen that happen in the past wave of disruption.
For example, when social media became [prevalent], you could see that people stopped reading stories and started summarising them. That was a significant change. And yes, people gained social media skills, but some of them also lost the ability to work with sources to the same degree, to look for interesting angles, and to create structures that would be more than just what the YouTube algorithm promotes. So that is a real risk in the new wave of disruption.
Q. What distinguishes AI-native newsrooms from those still experimenting with this technology?
A. First and foremost, leadership. Regardless of the size of the organisation, if there is a person in the leadership team who is curious and experimental, and who understands the depth of the opportunity as well as the disruption, that organisation will be more likely to adopt AI in a more systematic way, with a longer vision and horizon, and in more complex ways.
Some small media organisations out-adopt giants, at least among the cases that we know of. For example, Ukraine’s texty.org.ua, a nonprofit that specialises in data-based reporting and investigations, is in top the 10 AI adopters in the database. They not only build, but also open-source a lot of their tools.
The second factor is the type of organisation that you are looking at, which often dictates how people are going to adopt AI. The most interesting example comes from public service media. These organisations tend to adopt AI in very different ways. They are much more likely to train models. They are much more likely to adopt them for inclusion and minority languages, or to solve problems that commercial organisations are never going to solve, like accessibility for people with hearing issues.
Financial resources, the ability to hire and the ability to develop in-house massively impact how people adopt AI, with many exceptions where people are using resources smarter, or finding open-source tools and things like that. But I think leadership, type of organisation and other resources are probably the key factors.
Q. Does geography matter?
A. It does and the most striking example is China. China is very different because it’s extremely top-down, pervasive and synthetic. They adopt AI on a very deep level. They change models right away, build the tools into the whole system, and are much more likely to produce a whole synthetic lineup of information, materials and entertainment. They are based on home-made models, train them a lot more often, and the integration is so much deeper.
In Latin America, [the database suggests] they are much more likely to train their models because the existing models are riddled with biases and they are trying to improve that. Non-Western [news organisations are] much more likely to have synthetic presenters, whereas in the West it’s frowned upon. You don’t have avatars all that much. And if you do, it’s typically on the margins.
Q. Where do publishers see the value of AI for their organisations?
A. There are two aspects to this question. The first one is that data on measurements, KPIs and impact are extremely rare. There is simply very little of it in my database. That section is frequently empty or with some wishy-washy statement that they hope to improve efficiency in the newsroom. It doesn’t really give you anything.
The second aspect is that adoption is so heavily skewed towards production and the newsroom that the impact is going to be felt in the newsroom much sooner than on the commercial side. There are many reasons for that, including the fact that news media simply don’t have the same data on the commercial side. But it’s an opportunity that is very obviously going to be used at some point.
Q. Is there a pattern in the data that worries you about how AI is being implemented?
A. I recently posted about gender issues and avatars. The data on that is really bad. Synthetic people tend to be young, female, slim, perfectly fitting into the mainstream cultural ideal of the country where they are rolled out. They tend to be obedient and enforce every gender stereotype that you can think of. It’s really bad and (interestingly) universal. Anywhere you go (the MENA region, Latin America, wherever you look) news media make the same mistake, propagating the same stereotypes.
The differences go further when they recreate a person and create an avatar out of an existing person. Male personas tend to be authoritative historical figures, recreated for their authority, whereas for women, they are trying to extend the shelf life of a presenter and make the presenter work more hours, effectively.
This perpetuates exactly the same biases that exist in the real world, which is really scary. A year ago, there was a lot of conversation around how models themselves are trained in a way that makes them biased and how that’s impacting everything that’s developed further down the road. But the media industry is compounding those biases and disadvantages that exist in society, which is really scary.
Q. You may have seen more examples of AI adoption in journalism than anyone else. Is there any kind of conventional wisdom about AI in journalism that maybe is misunderstood?
A. I think the strategic importance of AI is still misunderstood. A lot of people in the media, despite thinking about AI, don’t quite get the degree of disruption they’ll be facing. Adoption is happening much faster right now than with the previous wave of disruption.
People don’t yet see that things are completely changing. I’m now seeing people talk about four paradigm shifts at the same time.
We used to think about our stories as stories, videos or posts on Facebook, just individual units of information that the recipient consumes as they were. Now those pieces of content become flow. Our work, or whatever we want to present, is going to be decomposed and picked up by people wherever they exist in their information flow, whether it’s in a chatbot or in a device based on AI.
Human agency in information consumption is going to change because of this intermediary layer. The trillion new users on the web, the next trillion, are going to be robots. So if news organisations want to be noticed, they need to work with that new agent.
You are seeing some organisations starting to think in that direction, but not enough, because it means different work, with a different set of priorities. These major shifts in the industry are not easy to comprehend and work towards. That’s something that the industry hasn’t quite started grappling with.
In every email we send you'll find original reporting, evidence-based insights, online seminars and readings curated from 100s of sources - all in 5 minutes.
In every email we send you'll find original reporting, evidence-based insights, online seminars and readings curated from 100s of sources - all in 5 minutes.